7 Best AI Code Interpreters & Data Analysis Tools for Developers (2026)
Most developers have the same story. You paste a messy CSV into a chatbot, ask for a quick summary, and get back a confident answer with numbers that don’t add up. The model never ran anything—it simply guessed.
That is the exact gap this guide addresses. The tools below don’t just talk about your data. They execute code against it, catch their own errors, and show you the exact result. We’ve compared seven of the best options on file limits, sandboxing, messy-data handling, privacy, and pricing so you can pick the right one without wasting a week on trials.
Quick Summary & Comparison
| Tool | Primary Strengths | Languages / Formats | Privacy & Security Level | Starting Price |
| ChatGPT Advanced Data Analysis | Native Python execution, fast charting | Python; CSV, XLSX, JSON, XML, YAML, TXT | Cloud sandbox; personal plans may train on data by default | Free tier (limited); paid plans from ~$20/mo |
| Julius AI | Dedicated data analyst, repeatable Notebooks | CSV, Excel, PDF; database connectors on higher plans | Cloud; stronger controls on Business/Enterprise | Free (15 messages/mo); paid from ~$20–$35/mo |
| Claude (code execution + Artifacts) | Clean logic, interactive visuals | Python and Node.js; CSV, TSV and other files | Cloud sandbox; network access controls | Free tier; paid plans and API usage |
| Hex | Collaborative SQL + Python notebooks | SQL, Python, R; warehouse connections | Enterprise SSO, audit logs, HIPAA on top tier | Free Community; Professional $36/editor/mo |
| Open Interpreter / OpenCode | Local execution, any model | Python, JS, Shell | Code runs on your machine; depends on the model API you pick | Free and open source (you pay for model tokens) |
| DeepSeek API | Very low cost per token | Whatever your own pipeline runs | Third-party API; check your data policy | Pay-as-you-go from ~$0.28 per million input tokens |
| Akkio | No-code predictive models | CSV and connected business data | Cloud SaaS; enterprise tier available | Basic ~$49/user/mo |
Note: Prices change frequently. Treat this table as a starting point and confirm details directly on each vendor’s pricing page before subscribing.
Why Standard AI Chatbots Fail at Real Data Analysis
A plain language model predicts text. It looks at your prompt, then produces the most plausible next words. When you ask it to average a column, it doesn’t perform a mathematical average—it writes something that looks like a calculated average.
While that approach might work for small, tidy examples, it completely collapses on real-world datasets.
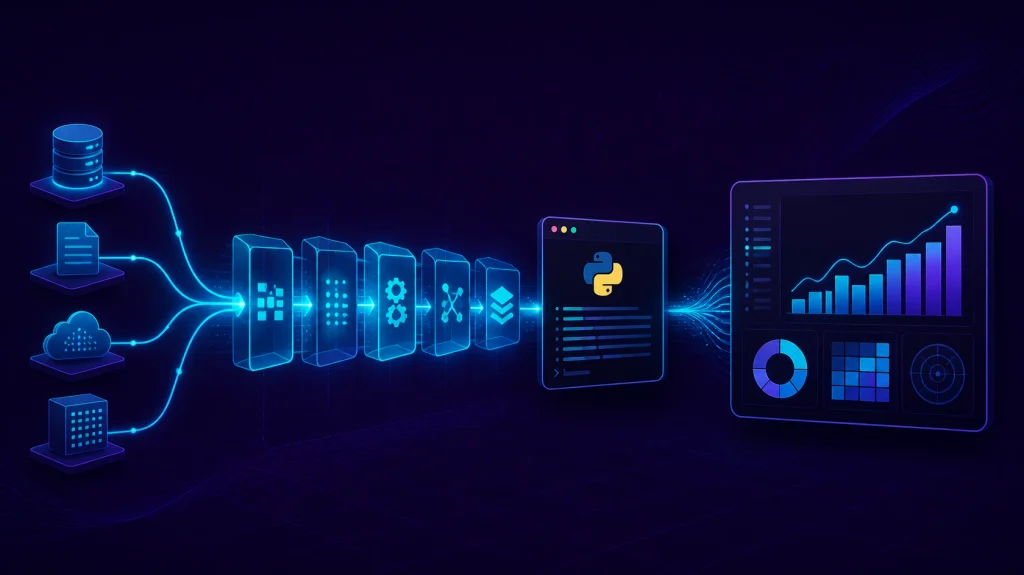
A true code execution environment changes the loop entirely. The model writes Python, a sandbox runs it, and the real output (or traceback error) returns to the model. Then the AI reads that output and decides what to do next. This is a REPL (Read-Eval-Print Loop) process, and it represents the difference between guessing and computing.
Key Technical Pillars for Accurate AI Data Analysis
- Sandboxed Execution: Code runs inside an isolated container—not on your laptop and not on the model’s primary server process. If code crashes or attempts an unauthorized action, the impact remains safely contained.
- Stateful Memory: Variables, loaded DataFrames, and imported libraries persist across prompts. You load a 200 MB file once and ask follow-up questions without re-uploading.
- Error Feedback: When Pandas throws a
KeyErrordue to a trailing space in a column header, the AI reads the error stack trace and fixes the code automatically. Standard chatbots without code execution cannot detect these issues.
One important caveat: Even with sandboxed execution, the AI writes the underlying script, meaning logical errors can still occur. A script that runs without errors can still output the wrong answer if the prompt or logic is flawed. Always review generated scripts for mission-critical tasks.
Deep Dive: Top 7 AI Code Interpreters & Data Analysis Tools
1. ChatGPT Advanced Data Analysis (Best for Native Python Execution & Charting)
Overview & Use Case: This is the tool most users think of when discussing code interpreters. You upload a dataset, ask questions in plain English, and ChatGPT writes and runs Python inside a sandbox. It remains the easiest starting point for ad-hoc analysis and rapid chart generation.
Key Features:
- Runs Python in a sandboxed container pre-loaded with standard data science libraries like pandas, numpy, and openpyxl.
- Accepts file uploads up to 512 MB, though practical limits for tabular data are tighter (~50 MB for stable analysis; files over 20 MB may occasionally encounter timeout errors).
- Reads CSV, XLSX, JSON, XML, YAML, TXT, and Markdown files.
- Paid plans feature limits around 10 million tokens per file, with Plus users receiving roughly 80 uploads per 3-hour window.
- Generates downloadable charts via Matplotlib and exports cleaned files directly.
Performance & Capabilities: Performs well on moderately messy data by identifying mixed date formats, calculating null counts, and executing data-cleaning steps before running analysis. Its ability to self-correct code execution errors minimizes manual troubleshooting.
However, RAM limitations inside the sandbox can occasionally trigger generic “Error analyzing file” messages without detailed diagnostics, making it difficult to distinguish between data errors and system caps.
- Pros: Fast setup, familiar UI, strong charting, and seamless multi-turn follow-ups.
- Cons: Vague error messages on large sheets, rolling upload limits, and default data-sharing on personal plans (unless opted out in Data Controls).
- Pricing: Free tier with limited analysis. Paid plans start at $20/mo, with Pro tiers at $100–$200/mo. Business and Enterprise tiers exclude data from model training by default.
2. Julius AI (Best Dedicated AI Data Analyst for Complex CSVs & Visualizations)
Overview & Use Case: Julius is built specifically for analyzing files and datasets without requiring code. It is an ideal solution for data analysts, founders, and developers seeking quick data insights without manually writing notebooks.
Key Features:
- Accepts CSV, Excel, and PDF uploads for interactive natural language queries and chart requests.
- Reusable Notebooks allow users to save analytical workflows as step-by-step sequences and re-run them on new datasets.
- Higher-tier plans include native connectors for databases (Snowflake, BigQuery, Postgres) and dbt integration.
- Performs advanced statistical tests, data merges, regressions, and predictive modeling alongside visualization.
Performance & Capabilities: Julius excels at multi-file analysis and complex statistical evaluations, producing clean, presentation-ready visualizations. When encountering messy data, it actively prompts users for clarification rather than silently dropping problematic rows.
For massive datasets (100,000+ rows), processing times may slow down or hit execution memory thresholds.
- Pros: Reproducible workflow notebooks, polished chart quality, accessible to non-technical users.
- Cons: Message credit caps on lower tiers, steep price increase between Pro (~$45/mo) and Business tiers, per-seat costs for teams.
- Pricing: Free plan includes 15 messages/mo. Plus starts at ~$20–$35/mo, Pro at ~$45/mo, with custom pricing for Enterprise. (Students receive 50% off).
3. Claude: Code Execution & Artifacts (Best for Clean Logic & Interactive Visuals)
Overview & Use Case: Claude runs Python and Node.js in a secure server-side sandbox, generating both static data outputs and interactive Artifacts (such as dynamic React dashboards and HTML UI components). It is ideal for developers who prioritize code readability and structural logic.
Key Features:
- Server-side sandboxed Python and Node.js execution within the web app and via the Anthropic API.
- Handles CSV, TSV, and text inputs, exporting visual outputs as clean graphics or interactive Artifacts.
- API sandbox provides isolated containers pre-installed with essential data science libraries (no default external network access).
- Network egress toggles and domain allowlists permit tight control over external connections.
Performance & Capabilities: Claude generates clean, well-documented code that is straightforward to audit. It explains the rationale behind data-cleaning decisions (such as handling missing values) rather than executing changes silently.
Its primary constraint is context scale—processing tens of thousands of raw text rows simultaneously may push context and file-size boundaries.
If you’re building content automation pipelines beyond code and data analysis, check out our step-by-step guide on 15+ Faceless YouTube Channel Ideas for 2026 (High-CPM Guide).
- Pros: Highly readable code output, interactive visual Artifacts, strong security and network controls.
- Cons: Not designed for massive big-data processing, tier-based usage caps.
- Pricing: Free tier available; paid Pro and Team plans increase usage allowances. API code execution is billed separately alongside token usage.
4. Hex (Best Enterprise Data Science & Collaborative Notebook Integration)
Overview & Use Case: Hex is a collaborative data workspace where SQL, Python, and R code cells live side-by-side. Featuring an integrated AI assistant (“Magic”), Hex is designed for data teams requiring governed, shareable, and scalable warehouse analysis.
Key Features:
- Multi-language notebook environment supporting SQL, Python, and R with native data warehouse connections.
- Converts technical notebooks into interactive data apps for non-technical stakeholders.
- Native AI assistant assists with query generation, code debugging, and automatic documentation.
- Enterprise-grade governance: SSO/SAML, SCIM user provisioning, audit logs, and HIPAA compliance options.
Performance & Capabilities: Hex excels when connecting directly to cloud data warehouses (Snowflake, BigQuery, Databricks). It accelerates boilerplate code generation while giving developers complete manual control over data transformations.
- Pros: Real-time team collaboration, publishable web apps, enterprise governance.
- Cons: Higher cost scaling for larger teams, overkill for simple one-off CSV checks.
- Pricing: Free Community plan (up to 5 notebooks). Professional starts at $36/editor/mo; Team tier is $75/editor/mo (14-day trial available).
5. Open Interpreter / OpenCode (Best Open-Source Local Execution for Privacy)
Overview & Use Case: Designed for privacy-conscious developers, Open Interpreter runs AI-generated code directly on your local machine, while OpenCode provides an open-source terminal coding interface. Both ensure sensitive data remains strictly on your local hardware.
(Note: Open Interpreter has been updated in Rust for lighter workflows—check current official documentation for setup changes).
Key Features:
- Executes Python, JavaScript, and Shell scripts locally using your system’s native environment.
- Model-agnostic architecture: Connects to local LLMs via Ollama/LM Studio or cloud APIs (OpenAI, Anthropic).
- Open-source licenses (Open Interpreter: Apache-2.0; OpenCode: MIT).
- Explicit permission prompts prior to executing local terminal commands.
Performance & Capabilities: Performance scales directly with your hardware rather than cloud sandbox limits. Large CSV files that hit cloud RAM limits run smoothly locally if your machine has sufficient memory. Data cleaning efficiency depends heavily on the chosen underlying model.
- Pros: 100% data privacy (data stays local), no cloud file-size caps, open-source flexibility.
- Cons: Requires manual setup; local execution carries security risks if unverified commands are approved.
- Pricing: 100% free software. Costs apply only if using paid cloud model API tokens.
6. DeepSeek API (Best Low-Cost API Execution for Large Data Pipelines)
Overview & Use Case: DeepSeek provides a low-cost, high-performance model API intended for integration into custom developer pipelines. It is optimal for batch processing, massive data classification, and automated script execution at scale.
Key Features:
- Highly competitive pay-per-token pricing (~$0.28 per 1M input tokens / ~$0.42 per 1M output tokens).
- Extended context window capabilities for processing long documents and dense data logs.
- Open-weights available for self-hosted infrastructure.
Performance & Capabilities: Delivers exceptional cost efficiency for automated data pipelines. Because the API does not include a built-in managed code execution sandbox, developers must build and manage their own local or containerized execution environment.
- Pros: Extremely low token costs, ideal for automated backend pipelines, open-weights available.
- Cons: Requires custom execution infrastructure; data privacy compliance must be verified per project.
- Pricing: Pure pay-as-you-go pricing based on token consumption.
7. Akkio (Best Predictive Analytics & AutoML for Non-Developers)
Overview & Use Case: Akkio is a no-code machine learning platform designed for operations teams, marketers, and business analysts. Users can upload tabular data, select a target column, and generate predictive models or forecasts within minutes.
Key Features:
- Automated model training for classification, lead scoring, forecasting, and anomaly detection.
- Direct integrations with CSV uploads and business data sources (HubSpot, Salesforce, Google Sheets).
- Rapid AutoML model generation without manual hyperparameter tuning.
Performance & Capabilities: Akkio provides the fastest route from raw tabular data to actionable predictive models without writing code. However, it offers limited transparency for custom feature engineering or exporting model binaries to custom code stacks.
- Pros: Ultra-fast setup, zero ML coding required, clean reporting tools.
- Cons: Black-box limitations for custom ML engineers, per-user SaaS pricing.
- Pricing: Basic tier starts around $49/user/mo; Pro tier at ~$99/user/mo.
How to Choose the Right AI Code Interpreter for Your Workflow
| Your Situation | Best Fit | Key Reason |
| Quick ad-hoc analysis & charts | ChatGPT, Claude, Julius AI | Fast setup, strong visual outputs, zero setup |
| Repeatable workflows without code | Julius AI Notebooks | Save and re-run analytical steps on new files |
| Enterprise data warehouses | Hex | Team collaboration, governance, data app publishing |
| Strict privacy / sensitive code | Open Interpreter / OpenCode | All code runs locally on your machine |
| High-volume automated pipelines | DeepSeek API | Lowest cost-per-token for custom backends |
| Predictive forecasting (No-Code) | Akkio | Fast AutoML models from spreadsheets |
Security & Data Privacy Warning for Developers
- Check Default Training Settings: Personal cloud plans (e.g., free/Plus ChatGPT) may use uploaded files for model training by default unless explicitly disabled in account settings.
- Sanitize Data Before Uploading: Strip PII (names, emails, financial records) and apply synthetic identifiers before sending files to cloud tools.
- Audit Generated Code: Review scripts prior to execution. Local tools run with user permissions—never run unverified commands outside a virtual machine or container.
- Enforce Network Restrictions: Where possible, restrict execution sandboxes from initiating external HTTP requests to prevent unauthorized data exfiltration.
- Protect API Credentials: Never paste database connection strings, secret keys, or authentication tokens into public chat interfaces.
Frequently Asked Questions (FAQs)
What is an AI code interpreter?
An AI code interpreter is an advanced LLM integration that writes code, executes it inside a sandboxed environment, and reads the execution output before delivering an answer. Unlike standard chatbots that guess text outputs, code interpreters compute exact calculations, manipulate DataFrames, and render charts programmatically.
Is it safe to upload company data to an AI code interpreter?
Safety depends on the vendor and plan tier. Enterprise and Business plans typically guarantee data privacy and exclude user inputs from model training. Personal tiers often retain data unless opted out. For sensitive data, use local tools (Open Interpreter) or enterprise-grade environments.
What is the practical maximum file size for AI code interpreters?
While tools like ChatGPT list limits up to 512 MB, practical performance caps for tabular data (CSVs, Excel) hover around 20 MB to 50 MB. Files exceeding these sizes often hit memory execution limits inside cloud sandboxes.
Which tool is best for strictly confidential or regulated data?
Open-source local tools like Open Interpreter or OpenCode paired with local models (via Ollama) ensure zero data leaves your local hardware.
Can AI code interpreters completely replace human data analysts?
No. While these tools accelerate data cleaning, exploratory analysis, and visualization, they do not replace human oversight. A human analyst must formulate the business questions, validate code logic, and verify that the output aligns with domain context.
Final Verdict: Which Tool Belongs in Your Dev Toolkit?
- Fastest Ad-Hoc Analysis: ChatGPT Advanced Data Analysis or Claude.
- Code-Free Repeatable Analysis: Julius AI.
- Warehouse Data Science Teams: Hex.
- Maximum Privacy & Local Code: Open Interpreter / OpenCode.
- High-Scale API Pipelines: DeepSeek API.
- No-Code Predictive Modeling: Akkio.
Final Thoughts
AI code interpreters have fundamentally changed how developers and data analysts interact with raw files. By shifting from text prediction to actual sandboxed code execution, these tools eliminate guesswork and deliver reliable, computing-backed results.
Start by choosing one cloud tool for rapid charting and one local solution for confidential data. Testing them on a sample CSV will quickly show which workflow fits your daily routine best.